If you care about kuzushiji, machine learning, or the challenge of reading premodern Japanese script, this dataset is a serious rabbit hole. It’s also a great reminder that Japanese text history isn’t just about pretty calligraphy, it’s about data, labels, and how computers learn to read what humans once wrote by hand.
Imagine a narrow alley in Tokyo. One shop sells vintage books, another has a stack of old postcards, and somewhere in the middle is a handwritten world that modern OCR still struggles to understand. That’s the kind of problem the Kuzushiji Kanji dataset tries to tackle, and honestly, I love that it exists.
Hosted on Kaggle as the Kuzushiji Kanji Image Dataset, it gives researchers and hobbyists a direct way to work with historical Japanese character forms. The headline numbers are the real hook: 3,832 kanji classes, 140,424 images, and every image scaled to 64x64 grayscale. Sounds small? For machine learning, that size is actually very practical, because it keeps experiments fast while still covering a huge range of characters.
What makes the Kuzushiji Kanji dataset so interesting
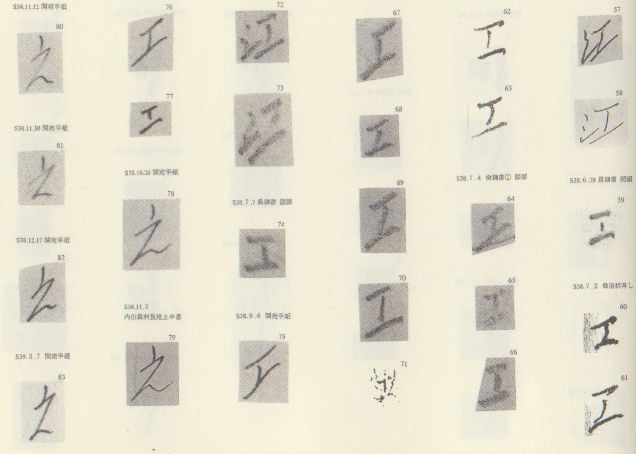
Ever wondered why old Japanese writing is such a headache for OCR? Kuzushiji is a cursive, highly stylised script used before modern printed Japanese became standard. A character can look surprisingly far from its modern form, and the same kanji may appear with different stroke shortcuts depending on the era, the writer, or the book.
For example, a learner who can read everyday Japanese might still stare at kuzushiji and feel completely lost. That’s not a failure, it’s just a different visual system. The dataset matters because it turns that old script into a structured computer vision task, where each image is tied to a class label, and models can be trained to recognise patterns across thousands of handwritten variants.
Let's be honest: this is where history stops being abstract and becomes measurable. You’re not just saying “old Japanese script is hard”, you’re giving a model 140,424 concrete examples and checking whether it can classify them correctly. Personally, I think that’s the part that makes the dataset so useful, because it connects cultural preservation with real technical work.
3,832 kanji classes, and why that number matters
Compared with back home, many OCR datasets are tiny or focused on modern fonts only. Here, the scale is much more demanding. 3,832 kanji classes means the dataset covers a very large character space, which is excellent for training recognition systems that need to distinguish between similar shapes, not just between easy, high-frequency symbols.
That class count also creates a nice challenge for learners who like Japanese writing history. You start noticing how many kanji forms can feel related at a glance, yet behave differently once they’re stylised. Speaking of which, that’s exactly the kind of visual confusion that makes kuzushiji so hard for humans and machines alike. A single stroke angle can change everything.
What machine learning people get from it
On the flip side, the dataset isn’t only useful for final models, it’s also great for testing data pipelines. Can your code load grayscale images properly? Can your classifier handle thousands of labels without collapsing into a mess of false positives? Can you benchmark a simple CNN against a stronger architecture and actually see the difference?
Here’s the deal: a dataset like this is ideal for experimentation because the image size is fixed at 64x64, which reduces noise in preprocessing. You can focus on classification, augmentation, model comparison, and error analysis instead of spending half your time resizing or cleaning wildly inconsistent image formats. Sounds good, right?
64x64 grayscale, and why the format is a smart choice
Picture this: you’re building an OCR project and your input data is all over the place. Some files are huge, some are blurry, some are too colourful, and your training run becomes a mess before it even starts. The Kuzushiji Kanji dataset avoids a lot of that pain by using 64x64 grayscale images.
That choice is simple, but it’s smart. Grayscale strips away colour distractions, which don’t matter much for character classification anyway, and the small resolution keeps training time manageable on normal hardware. For students, Kaggle users, or independent researchers, that means less friction and more actual model work.
Seriously though: this format also makes the dataset easier to compare with other handwriting benchmarks. If you want to test a baseline model, or even try transfer learning from a broader image model, the consistent 64x64 setup gives you a stable starting point. My tip: begin with a very plain classifier, then move to a more expressive architecture only after you understand where the errors come from.
Why Japan fans should care too
It’s early morning in Kyoto. You’re in a quiet bookshop, and a shelf of old texts catches your eye. That atmosphere is exactly what makes kuzushiji so compelling for Japan fans, because it links language learning to material culture, not just textbook grammar and JLPT vocab.
For learners, the dataset is a reminder that Japanese writing has layers. Modern kanji, hiragana, katakana, and historical scripts all sit in the same long story. If you know words like hon, jidai, and rekishi, this dataset gives those terms real texture. It also explains why museum labels, archive projects, and digitisation work matter so much in Japan.
What I especially like: this kind of resource makes the past feel technical, not dusty. The old pages are no longer just “old”. They become labelled images, train-test splits, and model predictions. That shift is huge, and it’s one reason OCR researchers keep returning to Japanese historical scripts. But that’s not all.
Frequently Asked Questions
What is the Kuzushiji Kanji dataset?
It is a Kaggle image dataset built for recognizing historical Japanese kanji forms.
How many classes and images does it contain?
It includes 3,832 kanji classes and 140,424 images.
What format are the images in?
The images are 64x64 grayscale files, which makes them convenient for machine learning experiments.
If you enjoy Japan topics that sit between language, history, and tech, this dataset is a great place to start. And if you want more Japan coverage, check out more Japan news on jpnerd.com.